AI call scoring: how Drellia audits every call
AI call scoring that checks every call and chat against your own questionnaires, links each alert to the exact quote and keeps your QA team in charge.
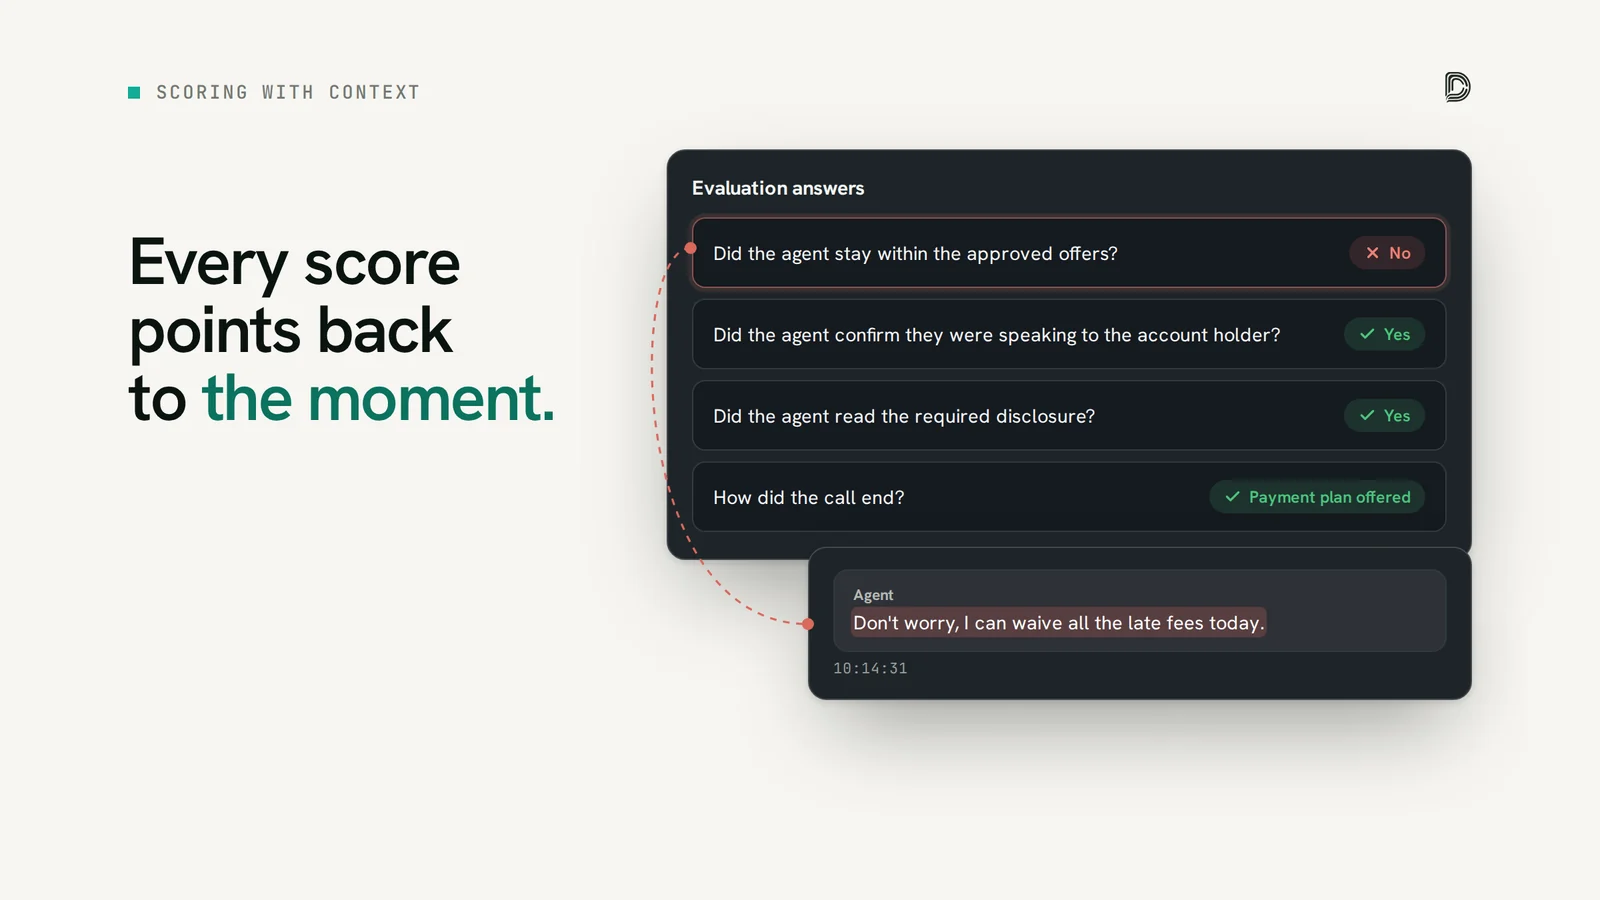
Quality assurance has always been a balancing act: you want consistent scoring, but you also need the context of each conversation. Manual QA alone can’t scale, and keyword-based automation often misses the bigger picture.
That’s why Drellia scores calls with AI against your own questionnaires: automation that saves time, covers every conversation and keeps the context.
How Drellia evaluates every conversation
Drellia transcribes each call and evaluates it, like every chat, against the questionnaires your team writes. For each question it records whether the answer is compliant. A question can check, for example:
- That a mandatory disclosure or compliance statement was read.
- That the agent followed a required step of the script.
- That the agent verified the customer’s identity before discussing the account.
Because every conversation is evaluated after it ends, you score every call, not a small sample. Drellia evaluates conversations in Spanish and English.
Your standards, written as questions
Every organization has its own standards, so Drellia doesn’t impose a generic scorecard. You write questionnaires with yes/no, multiple-choice and open questions, set the compliant answer for each, and describe what the evaluator should look for. Questions can:
- Check for required greetings or closing statements.
- Flag mentions of a competitor or brand-specific terms.
- Identify phrases your business prohibits.
This keeps the automation aligned with your brand’s standards and your regulators’ rules, not someone else’s.
Alerts that carry the evidence
When a conversation misses a question you flagged, Drellia raises a low, medium or high alert with the employee, the question and the quote from the conversation. Reviewers start with the failures that matter and can judge each alert from the quote, without replaying the whole call.
Consistent scoring without reviewer fatigue
Human reviewers get tired and apply criteria differently from one call to the next. An AI evaluation applies the same questionnaire to every conversation. With Drellia:
- Every call and chat is evaluated against the same questions.
- Supervisors see results as conversations are evaluated, instead of waiting for a weekly sampled review.
- Coaching starts from dashboards by employee and department, linked to the conversations behind them.
Supervisors stay in charge
AI doesn’t replace supervisors; it gives them better starting points. Each evaluation sits beside the transcript it is based on, and your QA team decides what to coach, what to escalate and when a questionnaire needs a clearer question.
Why it matters
- 100% coverage of calls and chats, not a sample.
- Your own criteria, written as questionnaires.
- Evidence with every alert, so people judge the cases that need judgment.
Book a demo to see Drellia audit your own calls.